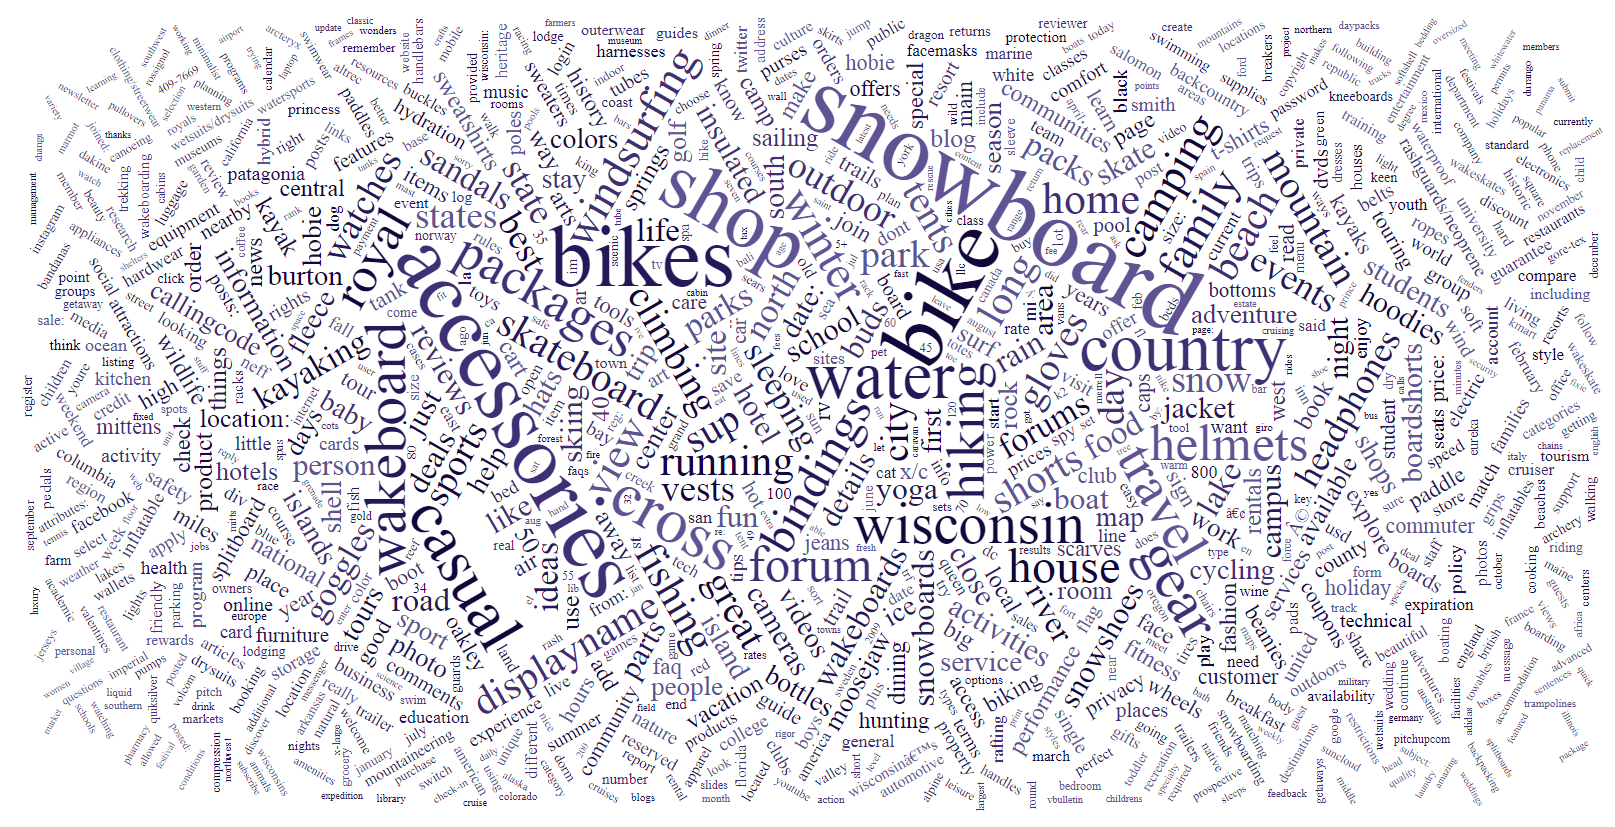
Big Data Series - SurfSara and the Common Crawl
A free-format project on the SurfSara Hathi cluster: running Spark over 1.73 billion crawled web pages to build word clouds around kayaking.
// 3 posts
A free-format project on the SurfSara Hathi cluster: running Spark over 1.73 billion crawled web pages to build word clouds around kayaking.
Poking at a Kaggle housing dataset in Spark: loading 292 columns, running SQL over it, and hunting for the Kremlin in the data.
A hello-world walk through Hadoop and HDFS: setting up a pseudo-distributed cluster and running the classic MapReduce word count on the complete Shakespeare.